GP2: A reproducible model with retry-safe local delivery
On this page
- Purpose, prerequisites, and limits
- Functional contract
- Milestones and testable acceptance criteria
- Hints before the solution
- Complete solutions: GP2
- Deriving the retry argument
- Model identity is part of operation identity
- Experiment procedure and interpretation
- Complete reference implementation
- What was actually fault-tested
- Failure diagnosis and tradeoffs
- Rubric and independent defense
Purpose, prerequisites, and limits#
Integrate data contracts, ML evaluation, immutable artifacts, and failure handling. Prerequisites are G04–G05, G08–G09, G11–G12, and G15. This is not an online game service, a production message broker, a financial transaction system, or a public prediction endpoint. It uses two local SQLite files and a synthetic two-feature grouped dataset. No network listener, credentials, cloud account, or real customer data is required.
Implement the experiment and local delivery workflow in starters/scoring.py. Preserve the group split and frozen model identity, make producer and consumer effects transactional, and demonstrate recovery after a worker dies after consumer commit but before producer acknowledgment. Submit the artifact, experiment report, test evidence, failure trace, and design limitations.
Functional contract#
Generate 30 synthetic groups with four rows per group using the fixed fixture. Split groups into training, validation, and test partitions. Fit mean/scale preprocessing only on training data. Train logistic candidates at regularization strengths using the fixed 400-step procedure. Select the candidate with lowest unregularized validation log loss, breaking ties by lower regularization strength. Freeze weights, bias, preprocessing, feature order, threshold , and schema version before inspecting test outcomes. Test metrics are descriptive evidence on this synthetic split, not real-world model utility.
The model artifact has exactly the keys schema, features, mean, scale, weights, bias, and threshold. It uses JSON, not executable serialization. The loader limits file size to 16 KiB and checks field shapes, finiteness, bounds, and feature order. A content digest identifies the exact canonical artifact; it is not a signature or authorization mechanism. Trusted local files remain part of the threat model.
A submission has a stable job ID, two finite bounded features, and the exact model digest. Repeating the same ID with the same canonical payload is a no-op. Reusing the ID with different features or a different model is an error. The worker must use the specified model, not whichever model happens to be newest. A missing or wrong artifact is a visible failure, not a silent fallback.
The recorded effect is one row in the consumer’s results table for each accepted job ID. The associated receipt and result must commit together. The producer’s job and outbox record must also commit together. Message attempts may repeat. The narrow guarantee is deduplication of this recorded effect under the stated storage and identity assumptions, not exactly-once message transmission or arbitrary external effects.
Milestones and testable acceptance criteria#
First, reproduce the synthetic split and baseline experiment, saving the report and frozen artifact. Second, submit and score one job through two local stores. Third, reject conflicting IDs and wrong artifacts. Fourth, terminate a worker in the specified failure window, reopen both stores, and retry. Finally, write the recovery argument and compare the implementation with the actual fault tests.
Acceptance includes disjoint group sets, training-only preprocessing, deterministic candidate selection, finite probabilities, exact artifact identification, duplicate replay without a second effect, rollback on interrupted transactions, visible lock errors, corruption rejection, and recovery after child-process termination. No particular test accuracy is required; a fabricated high score fails the scientific purpose even if the delivery code is correct.
Hints before the solution#
Draw the two transaction boundaries before writing the worker loop. Ask what remains on disk after each boundary and what a retry can safely infer. Receipt insertion and result insertion must not be separated by a commit. A producer acknowledgment is different from the consumer’s durable effect. An integrity hash does not authorize a job or protect against an adversary who can change both payload and hash.
Complete solutions: GP2#
Compare the first step where your work differs. A corrected answer is not yet an independent success.
GP2Show solution
Two local transactions with a recoverable gap
The producer has jobs(id,payload) and outbox(id,digest,ack).
The consumer has receipts(id,payload) and results(id,score,model). Primary keys enforce identity uniqueness; foreign keys relate outbox to jobs and results to receipts. Values are passed through parameterized SQL. The explicit connection mode leaves transaction boundaries to SQL BEGIN IMMEDIATE, COMMIT, and ROLLBACK. SQLite’s documented connection behavior is the implementation reference. [G-SQLITE]
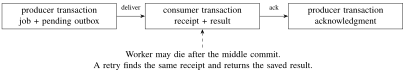
The arrow between stores is a local function call in this reference. The diagram models an asynchronous failure pattern but is not evidence that a network transport was deployed. Separate files make the absence of a single atomic commit across producer and consumer explicit.
Back to GP2Deriving the retry argument#
Before the producer commit, either no new job exists or both the job and its pending outbox record exist after successful commit. A failure inside that transaction rolls both back. The worker selects a pending record and validates its payload and model identity. The consumer transaction checks for an existing receipt. If none exists, it inserts both receipt and result, then commits. If the receipt exists with the same payload, it returns the already recorded result; with a conflicting payload it rejects the operation.
After consumer commit but before producer acknowledgment, the result exists while the producer still regards the job as pending. A restart will redeliver it. The consumer recognizes the same ID and payload and avoids inserting another effect. Only afterward does the producer mark the matching outbox digest acknowledged. If acknowledgment commits and a later worker finds no pending row, delivery is complete under this local contract.
The invariant is not “the worker runs once.” It may run several times. The invariant is that an accepted identity is bound to one immutable payload and has at most one matching result record, with a receipt committed in the same consumer transaction. Atomicity and the uniqueness constraint cooperate; a pre-insert application check outside a transaction is not an equivalent concurrency control.
A concurrent duplicate consumer attempt is serialized by SQLite’s write transaction acquisition. The reference’s short busy timeout exposes contention to the caller; it does not implement an unbounded retry storm. A future transport should add bounded backoff, retry budgets, observability, and poison-message handling according to its failure model. Those production features are not silently implied by the local loop.
Model identity is part of operation identity#
Suppose a job’s features score under model A and under model B with threshold . Replacing A by “latest” on a retry changes the decision while preserving the apparent job ID. The payload therefore includes the artifact digest, and the consumer validates the provided artifact against it. The result also records that digest so an investigation can identify the model used.
Canonical JSON uses sorted keys, compact separators, and rejection of nonfinite numbers. Submission converts the two feature numbers into a consistent floating representation. The fingerprint is about these exact serialized semantics; it does not prove semantic equality of arbitrary different model formats. The feature order must be fixed because swapping equal-length columns can silently produce wrong predictions.
An artifact should also carry lineage and richer metadata in a larger system, but extra fields change the declared schema and validation rules. Do not alter the reference schema without updating the tests and interfaces. The educational fixed schema is intentionally narrow, not a universal model registry design.
Experiment procedure and interpretation#
Training uses only training rows and their fitted scaler. Validation selects among the predeclared candidates. Test probabilities and confusion-based metrics are first computed after this choice. The saved report includes seed, row/group partitions, selected regularization, validation loss, test metrics, and artifact digest. The synthetic generator contains signals and randomness by design; a successful fit demonstrates the pipeline can use this toy structure, not that it predicts real player behavior.
Avoid repeatedly tuning against the saved test report. Reproducing an unchanged experiment verifies its computation; revising choices after inspecting its test outcomes turns that test into development information. For a new scientific comparison, declare the new protocol and use appropriate new evaluation evidence. G11’s risk review is required before attaching real actions to scores, even when the numerical pipeline is correct.
Complete reference implementation#
The file imports G12’s ml.py, G11’s ethics.py, and G15’s data.py, all printed in their solution sections and included in the archive. Run python -m solutions.scoring demo output/demo from the code directory. The directory is local; use a fresh output path to avoid mixing runs.
Fault-injection warning. The crashworker test subcommand deliberately exits its child process with code 23 after consumer commit. Run it only through the supplied subprocess test or as a disposable command, not by calling its crash option in a valuable interactive Python session. It does not kill unrelated processes.
"""GP2: reproducible synthetic experiment and retry-safe local recorded effects.
The crashworker CLI deliberately exits only its own process with status 23.
"""
from contextlib import contextmanager
from pathlib import Path
import argparse
import hashlib
import json
import math
import os
import re
import sqlite3
from . import data, ml, ethics


FEATURES = ["x0", "x1"]
ARTIFACT_KEYS = {"schema","features","mean","scale","weights","bias","threshold"}


def canonical(value):
    return json.dumps(value,sort_keys=True,separators=(",",":"),allow_nan=False)


def fingerprint(value):
    return hashlib.sha256(canonical(value).encode("utf-8")).hexdigest()


def finite_number(value, limit=1e6):
    return type(value) in (int,float) and math.isfinite(value) and abs(value) <= limit


def validate_artifact(artifact):
    if type(artifact) is not dict or set(artifact) != ARTIFACT_KEYS:
        raise ValueError("unexpected model schema keys")
    if type(artifact["schema"]) is not int or artifact["schema"] != 1 or artifact["features"] != FEATURES:
        raise ValueError("wrong schema version or feature order")
    for key in ("mean","scale","weights"):
        if type(artifact[key]) is not list or len(artifact[key]) != 2:
            raise ValueError("two model dimensions required")
        if not all(finite_number(x) for x in artifact[key]):
            raise ValueError("invalid numeric vector")
    if any(x < 1e-12 for x in artifact["scale"]):
        raise ValueError("scale too small")
    if not finite_number(artifact["bias"]) or not finite_number(artifact["threshold"]) or not 0 <= artifact["threshold"] <= 1:
        raise ValueError("invalid bias or threshold")
    return artifact


def _unique_object(pairs):
    result = {}
    for key,value in pairs:
        if key in result:
            raise ValueError("duplicate JSON key")
        result[key] = value
    return result


def load_artifact(path):
    with open(path,"rb") as handle:
        raw = handle.read(16385)
    if len(raw) > 16384:
        raise ValueError("artifact exceeds 16 KiB")
    try:
        value = json.loads(raw,object_pairs_hook=_unique_object)
    except (UnicodeError,json.JSONDecodeError) as error:
        raise ValueError("invalid artifact JSON") from error
    return validate_artifact(value)


def experiment(seed=21):
    rows = data.fixture(seed=seed)
    groups = [row["group"] for row in rows]
    parts = data.split_groups(groups,seed=seed)
    X = {name:[rows[i]["x"] for i in indices] for name,indices in parts.items()}
    y = {name:[rows[i]["y"] for i in indices] for name,indices in parts.items()}
    scaler = data.fit_scaler(X["train"])
    scaled = {name:data.transform(values,scaler) for name,values in X.items()}
    candidates = []
    for lam in (0.,.1,1.):
        model = ml.fit(scaled["train"],y["train"],lam=lam,rate=.1,steps=400)
        loss,_,_ = ml.loss_gradient(model["weights"],model["bias"],
                                  scaled["validation"],y["validation"],lam=0.)
        candidates.append((loss,lam,model))
    validation_loss,selected,model = min(candidates,key=lambda item:(item[0],item[1]))
    artifact = {"schema":1,"features":list(FEATURES),"mean":scaler["mean"],
                "scale":scaler["scale"],"weights":model["weights"],
                "bias":model["bias"],"threshold":.5}
    validate_artifact(artifact)
    identity = fingerprint(artifact)  # freeze before evaluating the test set
    probabilities = ml.predict(model,scaled["test"])
    metrics = ethics.binary_report(y["test"],probabilities,threshold=.5)
    report = {"seed":seed,"partitions":parts,
              "group_partitions":{name:sorted({groups[i] for i in indices})
                                  for name,indices in parts.items()},
              "selected_regularization":selected,"validation_log_loss":validation_loss,
              "test_metrics":metrics,"model_digest":identity,
              "limitation":"synthetic grouped data, not evidence of real-world utility"}
    return artifact,report


def connect_store(path, role):
    if role not in ("producer","consumer"):
        raise ValueError("unknown store role")
    connection = sqlite3.connect(path,timeout=.1,isolation_level=None,
                                 autocommit=sqlite3.LEGACY_TRANSACTION_CONTROL)
    connection.execute("PRAGMA foreign_keys=ON")
    connection.execute("PRAGMA synchronous=FULL")
    if role == "producer":
        connection.executescript("""
            CREATE TABLE IF NOT EXISTS jobs(id TEXT PRIMARY KEY,payload TEXT NOT NULL);
            CREATE TABLE IF NOT EXISTS outbox(
              id TEXT PRIMARY KEY REFERENCES jobs(id),digest TEXT NOT NULL,
              ack INTEGER NOT NULL CHECK(ack IN (0,1)));
        """)
    else:
        connection.executescript("""
            CREATE TABLE IF NOT EXISTS receipts(id TEXT PRIMARY KEY,payload TEXT NOT NULL);
            CREATE TABLE IF NOT EXISTS results(
              id TEXT PRIMARY KEY REFERENCES receipts(id),
              score REAL NOT NULL CHECK(score>=0 AND score<=1),model TEXT NOT NULL);
        """)
    return connection


@contextmanager
def transaction(connection):
    connection.execute("BEGIN IMMEDIATE")
    try:
        yield
        connection.execute("COMMIT")
    except BaseException:
        if connection.in_transaction:
            connection.execute("ROLLBACK")
        raise


def payload_for(job_id, features, model_digest):
    if type(job_id) is not str or re.fullmatch(r"[A-Za-z0-9_-]{1,64}",job_id) is None:
        raise ValueError("invalid job ID")
    if type(features) not in (list,tuple) or len(features) != 2 or not all(finite_number(x) for x in features):
        raise ValueError("two finite bounded features required")
    if type(model_digest) is not str or re.fullmatch(r"[0-9a-f]{64}",model_digest) is None:
        raise ValueError("invalid model digest")
    return {"id":job_id,"features":[float(x) for x in features],"model":model_digest}


def submit(connection, job_id, features, model_digest):
    payload = canonical(payload_for(job_id,features,model_digest))
    digest = hashlib.sha256(payload.encode()).hexdigest()
    with transaction(connection):
        old = connection.execute("SELECT payload FROM jobs WHERE id=?",(job_id,)).fetchone()
        if old is not None:
            if old[0] != payload:
                raise ValueError("conflicting job ID")
            return False
        connection.execute("INSERT INTO jobs VALUES(?,?)",(job_id,payload))
        connection.execute("INSERT INTO outbox VALUES(?,?,0)",(job_id,digest))
    return True


def consume(connection, payload, artifact):
    validate_artifact(artifact)
    raw = json.loads(payload,object_pairs_hook=_unique_object)
    if type(raw) is not dict or set(raw) != {"id","features","model"}:
        raise ValueError("invalid payload keys")
    normalized = payload_for(raw["id"],raw["features"],raw["model"])
    if canonical(normalized) != payload or raw["model"] != fingerprint(artifact):
        raise ValueError("noncanonical payload or wrong model")
    scaled = data.transform([raw["features"]],{"mean":artifact["mean"],"scale":artifact["scale"]})
    probability = ml.predict(artifact,scaled)[0]  # pure computation outside write lock
    with transaction(connection):
        old = connection.execute("SELECT payload FROM receipts WHERE id=?",(raw["id"],)).fetchone()
        if old is not None:
            if old[0] != payload:
                raise ValueError("consumer identity conflict")
            result = connection.execute("SELECT score,model FROM results WHERE id=?",(raw["id"],)).fetchone()
            if result is None:
                raise RuntimeError("receipt/result invariant violated")
            return {"id":raw["id"],"score":result[0],"model":result[1]}
        connection.execute("INSERT INTO receipts VALUES(?,?)",(raw["id"],payload))
        connection.execute("INSERT INTO results VALUES(?,?,?)",(raw["id"],probability,raw["model"]))
    return {"id":raw["id"],"score":probability,"model":raw["model"]}


def worker(producer_path, consumer_path, artifact, crash_after_consumer=False):
    if Path(producer_path).resolve() == Path(consumer_path).resolve():
        raise ValueError("use separate producer and consumer files")
    producer = connect_store(producer_path,"producer")
    consumer = None
    try:
        consumer = connect_store(consumer_path,"consumer")
        row = producer.execute("""SELECT j.id,j.payload,o.digest FROM jobs j
          JOIN outbox o ON j.id=o.id WHERE o.ack=0 ORDER BY j.id LIMIT 1""").fetchone()
        if row is None: return None
        job_id,payload,digest = row
        if hashlib.sha256(payload.encode()).hexdigest() != digest:
            raise ValueError("outbox integrity mismatch")
        result = consume(consumer,payload,artifact)
        if crash_after_consumer:
            os._exit(23)  # explicit disposable child-process test only
        with transaction(producer):
            changed = producer.execute("UPDATE outbox SET ack=1 WHERE id=? AND digest=?",
                                       (job_id,digest)).rowcount
            if changed != 1: raise RuntimeError("ack identity mismatch")
        return result
    finally:
        if consumer is not None: consumer.close()
        producer.close()


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    sub = parser.add_subparsers(dest="command",required=True)
    demo = sub.add_parser("demo")
    demo.add_argument("directory")
    crash = sub.add_parser("crashworker")
    crash.add_argument("producer");crash.add_argument("consumer");crash.add_argument("artifact")
    args = parser.parse_args()
    if args.command == "crashworker":
        worker(args.producer,args.consumer,load_artifact(args.artifact),crash_after_consumer=True)
        return
    root = Path(args.directory)
    root.mkdir(parents=True,exist_ok=False)
    artifact,report = experiment()
    (root/"model.json").write_text(canonical(artifact),encoding="utf-8")
    (root/"experiment.json").write_text(json.dumps(report,indent=2),encoding="utf-8")
    producer = connect_store(root/"producer.db","producer")
    try: submit(producer,"example-1",[.3,-.2],fingerprint(artifact))
    finally: producer.close()
    print(worker(root/"producer.db",root/"consumer.db",artifact))
    print("Saved local experiment to",root)


if __name__ == "__main__":
    main()
What was actually fault-tested#
The suite runs the crash path in a separate Python process, confirms its exit code, opens the consumer store to verify one result, and checks the producer remains unacknowledged. It then retries using fresh connections and verifies that the result count remains one while the acknowledgment becomes one. Additional tests reject conflicting payloads and wrong models, exercise a busy write lock, and induce an insertion failure to check that a receipt does not survive without its result.
This is actual process termination and reopen evidence, not merely a comment saying “imagine a crash.” It is still not a power-loss, filesystem-corruption, multi-host deployment, malicious-writer, or replicated-storage test. synchronous=FULL states a database setting; the current experiments do not certify storage hardware behavior under power failure. Changing the storage engine or transport invalidates parts of the operational argument until rechecked.
Failure diagnosis and tradeoffs#
A wrong digest or schema is a permanent validation failure under this job contract, not a reason for infinite retries. A busy database is potentially transient; use a bounded retry policy outside the transaction. A process death after consumer commit is an unknown-outcome window repaired by deduplication. A missing model version needs an explicit retrieval or rejection policy, never an implicit latest-model substitution.
A classroom consumer computes a pure score before opening its write transaction, reducing lock duration. If scoring had external side effects, this placement would need redesign. Results and receipts are retained indefinitely here; deleting them while retries remain possible can reintroduce duplicates. The demo does not implement retention, authentication, encryption, network backpressure, multiple tenants, or exactly-once external notifications. Those omissions define the boundary of the assigned system.
Rubric and independent defense#
Evaluate the data/evaluation contract, model reproducibility, transaction invariants, failure tests, and communication separately. A high test accuracy cannot compensate for leakage. A correct duplicate check cannot compensate for separately committed receipts and effects. An independently adequate submission explains every crash window, predicts the result of a duplicate with changed features, and identifies an assumption that would fail under a different storage system.
Unassigned extensions. Add a local socket transport with framing and a bounded queue, model-artifact signing using established libraries, retention with a specified retry horizon, or controlled multi-worker experiments. Each changes the threat/failure model and needs new tests and arguments. None is counted as implemented production capability in this edition.