C09: Bits, instructions, caches, and virtual memory
On this page
- A. Prerequisites and observable goals
- B. The central question: how can the same bits mean different things?
- C. Floating-point numbers represent a scaled significand
- D. Boolean circuits and instruction execution
- E. From one source function to actual generated assembly
- F. Locality, caches, and address translation
- G. Independent practice
- H. Complete solutions: C09
- I. Retention and readiness
A. Prerequisites and observable goals#
C01–C03 values, types, and lifetimes; C04 Boolean logic.
Decode integer and floating-point representations, distinguish language rules from compiler and hardware choices, trace a cache model, and explain how source code becomes an executable.
Level: Degree core; one concrete x86-64 example, not a universal assembly language.
B. The central question: how can the same bits mean different things?#
A bit is a binary digit. Eight bits can encode an unsigned integer from 0 through 255, a signed value under a chosen representation, a character-code fragment, or part of an instruction. The bits do not carry their interpretation independently of the type, protocol, or program. Hexadecimal groups four bits per digit: . Binary and hexadecimal are numeral systems, not different underlying quantities.
For an -bit unsigned representation, values range from 0 to . In an -bit two’s-complement interpretation, a bit pattern with unsigned value represents ; otherwise it represents . For eight bits, unsigned but signed. Addition at the bit level may produce the same low bits, while the language’s signed and unsigned overflow semantics differ.
In C++, unsigned arithmetic wraps modulo for its type. Signed arithmetic overflow is undefined behavior, not a promised wraparound operation. Mathematical integers have no fixed maximum; Python integers grow with available memory and arithmetic cost. A safe implementation must choose whether overflow is impossible by a proved bound, explicitly checked, saturating by a specified algorithm, or intentionally unsigned modular arithmetic. Merely hoping a large value will not occur is not a contract.
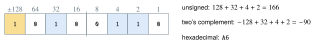
1010 0110 is A6 in hexadecimal. Read as an unsigned integer, the leading bit is worth and the value is . Read in two’s complement, that bit is worth and the value is . The bits are identical; the type decides the meaning.C. Floating-point numbers represent a scaled significand#
A common IEEE binary32 value has one sign bit, eight exponent bits, and 23 stored fraction bits. A normal finite value has the form . Binary64 uses one sign bit, eleven exponent bits, and 52 stored fraction bits with a different exponent bias. Special exponent encodings represent subnormals, infinities, and NaNs. The spacing grows with magnitude, so adding a small number to a very large one can leave the represented value unchanged.
The fraction has a factor 5 in its reduced denominator, so its binary expansion does not terminate. A finite binary floating-point representation of 0.1 is therefore an approximation. Equality comparisons between independently rounded calculations require thought: use exact comparisons when the representation and contract justify them, and scale-aware tolerances when comparing numerical approximations. NaN is not equal to itself under ordinary IEEE comparisons, so floating-point “equality” is not a mathematical equivalence relation over all bit patterns. A tolerance relation such as is generally not transitive either.
Endianness describes the order of bytes in a multibyte representation, not which mathematical value the programmer intended. A network format must specify byte order, widths, signedness, and encoding. Serializing a native C++ object by copying its raw bytes can leak padding and depend on platform layout; C12 instead uses an explicit length prefix.
D. Boolean circuits and instruction execution#
Logic gates realize Boolean operations in a hardware abstraction. A one-bit full adder takes , producing
For , the sum bit is zero and the carry is one, representing binary 10. Connecting carry outputs to later bit positions builds a multi-bit addition circuit. Actual processors use more sophisticated arrangements for performance, but the logical input-output relation remains the object to verify.
At a conceptual level, a processor fetches an instruction, decodes it, reads operands, executes an operation, and updates architectural state. Registers hold small amounts of directly accessible state; a program counter identifies instruction flow. Pipelines overlap stages for different instructions. Out-of-order and speculative execution can schedule work before earlier instructions retire while preserving required architectural behavior. Branch prediction attempts to keep work flowing; misprediction can discard speculative work. These mechanisms affect performance and sometimes security, but a C++ source statement is not guaranteed to correspond to one instruction.
E. From one source function to actual generated assembly#
The companion includes this complete source:
// C09: defined modulo-2^32 addition when uint32_t exists.
#include <cstdint>
std::uint32_t add(std::uint32_t a, std::uint32_t b) {
    return a + b;
}
On the recorded Linux x86-64 environment, GCC 14.2.0 with -std=c++20 -O2 -S emitted the central instructions
leal (%rdi,%rsi), %eax
ret
Under this example’s System V calling convention, the arguments arrive through registers whose low 32 bits are used, and the result is returned in eax. Here lea performs arithmetic address calculation without loading memory from that address. This is an observed compiler choice for the tiny function, not a C++ requirement or a promise about Windows calling conventions. The complete emitted assembly is saved in the verification directory.
A typical build preprocesses includes and macros, compiles each translation unit, assembles object code, and links objects with required libraries and symbol definitions. A missing declaration, a type error, an unresolved external symbol, and a runtime fault belong to different stages. Calling conventions determine argument passing, return values, and register responsibilities. Stack frames conceptually preserve call-local state, but optimized code may omit a frame pointer, inline a call, or keep values in registers. C02’s call-stack diagram describes semantic dependencies, not an invariant physical layout under optimization.
F. Locality, caches, and address translation#
A cache stores recently used memory blocks. Temporal locality means reusing data; spatial locality means accessing nearby addresses. A cache line is a transfer unit whose size is hardware-specific; the lab deliberately models 64-byte lines and four direct-mapped slots. An address maps to a block number by integer division by 64, to a slot by block number modulo four, and to a tag distinguishing blocks that share a slot.
For addresses , accesses to 0 and 4 initially share one line. Address 256 maps to the same slot as zero but a different tag, evicting it. Returning to zero misses again. This model illustrates compulsory and conflict behavior; it is not a model of every real cache’s associativity, prefetching, coherence, or replacement policy.
Virtual memory maps process-visible virtual addresses to physical memory through page tables and translation hardware. A TLB caches translations. A TLB miss is not necessarily a page fault, and a data-cache miss is not a page fault. Pages may be absent, protected, or shared according to the operating system’s mappings. A pointer’s numeric value is not a disk location and does not reveal ownership or lifetime. C10 connects this representation to processes and resource management. [OSTEP]
Multicore execution can run work in parallel, but serial work and coordination limit speedup. If fraction remains serial and the remainder divides perfectly across workers, ideal speedup is . Real communication, load imbalance, and contention can make it worse. GPUs emphasize large parallel workloads and throughput, with their own execution and memory organization; T02 adds measured data-movement reasoning rather than assuming a GPU always wins.
G. Independent practice#
F foundation C standard course work T transfer S optional stretch L runnable lab or project. Attempt the complete set before opening its solutions.
Decode 11111110 as an unsigned eight-bit integer and as a two’s-complement signed integer. Encode decimal 42 in binary and hexadecimal. Explain why interpretation is part of the contract.
Explain why 0.1 has no finite binary expansion. Why can a == a fail for a floating-point value, and why is “within epsilon” not generally an equivalence relation?
Trace the six-address cache example, recording block, slot, hit/miss, and evictions. State what this simplified model does not establish about the machine the reference run used.
A 100 ms computation has 20 ms of inherently serial work and 80 ms that parallelizes perfectly. Find the ideal runtime with four workers and the infinite-worker speedup limit. Then name three reasons a real measurement could be worse.
Implement the signed-eight-bit decoder, binary32 bit inspector, and direct-mapped cache simulator in representation_lab.py. Reject values outside the decoder’s domain and invalid addresses. Verify the bits of 1.0, the signed interpretation of 254, and the six-address cache trace. Keep the simulator’s assumptions explicit.
Optional small hints
C09.02: a reduced denominator must divide some power of two to have a finite binary expansion. C09.03: block 4 and block 0 share slot zero.
H. Complete solutions: C09#
Compare the first step where your work differs. A corrected answer is not yet an independent success.
C09.01Show solution
Same pattern, different signed interpretation
The unsigned value is . The signed two’s-complement value is . Decimal 42 is , so its binary representation is in eight bits and its hexadecimal representation is 2A. None of these digit strings alone says whether the application expects a signed number, a byte count, or another encoding; the type and protocol provide that meaning.
C09.02Show solution
Representability and relation properties
A finite binary fraction is an integer divided by a power of two. Since in lowest terms has a factor 5 in its denominator, no such finite representation equals it exactly. For NaN, ordinary IEEE equality is false even when comparing the value with itself, violating reflexivity of mathematical equality. A tolerance relation is not transitive: with tolerance 1, values 0 and 0.75 are close, and 0.75 and 1.5 are close, but 0 and 1.5 are not. Approximate comparison is a tool for a specified numerical task, not an automatic replacement for exact equivalence classes or ordered-container comparators.
Back to C09.02C09.03Show solution
A concrete cache-state trace
The blocks are and slots are . Starting empty, outcomes are miss, hit, miss, hit, miss, miss. The fifth access replaces block 0 with block 4 in slot zero; the sixth replaces block 4 with block 0. Total misses are four. This establishes only the stated direct-mapped model’s behavior. It does not measure the host processor’s real cache hierarchy, prefetcher, associativity, virtual-to-physical mapping, or timing.
Back to C09.03C09.04Show solution
The serial fraction remains
Ideal runtime is ms, for speedup . With infinitely many workers, runtime approaches 20 ms and speedup approaches 5. Synchronization overhead, memory-bandwidth saturation, unbalanced work, thread scheduling, cache coherence, or extra data movement can reduce the achieved speedup. The formula assumes the parallel portion itself does not grow with worker count and the original work remains equivalent.
Back to C09.04C09.05Show solution
Reference representation experiments
"""C09.05: explicit representations and a direct-mapped cache simulator."""
import struct

def signed8(bits: int) -> int:
    if type(bits) is not int or not 0 <= bits <= 255:
        raise ValueError("one byte required")
    return bits if bits < 128 else bits - 256

def float32_bits(value: float) -> str:
    raw = struct.unpack(">I", struct.pack(">f", value))[0]
    return f"{raw:032b}"

def cache_misses(addresses: list[int], line_bytes: int = 64,
                 slots: int = 4) -> int:
    if line_bytes <= 0 or slots <= 0:
        raise ValueError("positive geometry required")
    tags: list[int | None] = [None] * slots
    misses = 0
    for address in addresses:
        if type(address) is not int or address < 0:
            raise ValueError("nonnegative integer byte address required")
        block = address // line_bytes
        slot = block % slots
        if tags[slot] != block:
            misses += 1
            tags[slot] = block
    return misses

if __name__ == "__main__":
    print(signed8(254), float32_bits(1.0))
    print(cache_misses([0, 4, 64, 0, 256, 0]))
The signed decoder explicitly applies the interpretation to the upper half of the byte range. The bit inspector uses an explicit byte order for packing/unpacking, so its result is an encoding observation rather than an unexamined native-memory dump. The cache simulator retains tags for each direct-mapped slot and counts a miss whenever the requested block differs. The tests verify known representations and the predicted trace. The assembly example was separately compiled on the recorded platform; cross-platform compiler behavior is not claimed.
Back to C09.05I. Retention and readiness#
Retrieve mathematical versus machine integers, function-call semantics, and operation-count versus timing analysis. Advance when you can identify whether a claim belongs to mathematics, language semantics, compiler output, an ABI, or a hardware measurement.