G13: Neural computation and backpropagation you can derive
On this page
- Prerequisites and observable goals
- The central question: how does one parameter affect the final loss?
- Derive the reverse pass, one dependency at a time
- A fully numerical backward trace
- Gradient checking is an experiment on a derivative implementation
- Optimization difficulties do not disappear when gradients are correct
- Independent practice
- Smallest useful hints
- Complete solutions: G13
- Readiness and continuation
Prerequisites and observable goals#
G05 and G12; multivariable chain rule; arrays and nested loops.
Trace a network forward and backward, implement analytic gradients, challenge them with finite differences, and distinguish optimization failure from evaluation failure.
The central question: how does one parameter affect the final loss?#
A neural network is a composition of parameterized functions. Backpropagation is an efficient application of the chain rule to that composition. It does not infer a gradient by trying random weight changes, and it does not make the loss surface convex. Start with one hidden layer whose sizes and intermediate states remain visible. The model here is deliberately small enough to implement without a framework. The CS229 course treatment provides a reference for the chain rule and neural objectives. [G-ML]
For one example, use column vectors , hidden width , matrix , hidden bias , output weights , and scalar output bias :
The hyperbolic tangent acts separately on each coordinate. The hidden activation is not a class probability. The output is a logit; only is interpreted as a Bernoulli probability under the model. For target , use the stable logit loss from G12. Every arrow is a function with an input shape, output shape, and derivative.
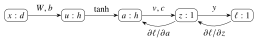
This is a dependency graph, not a memory-address drawing. The reverse arrows carry sensitivities. They do not mean the forward values are recomputed with reversed signs. Store the forward values needed by the derivative, or deliberately recompute them with a documented time–memory tradeoff.
Derive the reverse pass, one dependency at a time#
G12 gives . Since ,
Next, , so
In matrix form, , an -by- outer product. Taking a dot product here would produce the wrong object. The gradient with respect to , when needed, is ; the training lab updates parameters, not the input examples.
For the average objective over examples, divide each example’s sensitivity by , then accumulate every example’s contribution. The implementation chooses this convention inside the loop. If you also divide the completed gradient by afterward, you have divided twice. If a parameter is used along two graph paths, sum both contributions. Shared weights make addition essential; assignment that overwrites an earlier gradient loses part of the chain rule.
The lab adds but not bias penalties. Thus it adds and exactly once, outside the example loop. Adding the full regularizer for every example would change its effective strength with dataset size.
A fully numerical backward trace#
Take one input , one hidden unit, , with no penalty. The forward pass gives and loss . Now move backward:
The zero output-weight gradient does not imply the entire network gradient is zero. The hidden activation is zero, but changing the incoming weight would change that activation and therefore the final logit. With learning rate , a simultaneous update gives . These updates all use the same old forward state.
A tempting incorrect implementation first changes and then uses its changed value to compute . It is no longer calculating the gradient of the original parameter state. Finish the backward pass, retain its gradient, and only then update all parameters.
Gradient checking is an experiment on a derivative implementation#
For a parameter coordinate , central differences use
The vector has a one at coordinate and zeros elsewhere. Only one parameter changes in each numerical comparison. In smooth exact arithmetic the truncation error is typically under the required third-derivative bound. Floating-point subtraction and rounding compete with that error as gets very small. There is no rule that the smallest representable step is best.
Compare the analytic and numerical results using an explicit scale, for example
This quantity combines an absolute tolerance for small derivatives with relative scaling for large ones. State the formula; calling it simply “relative error” conceals the floor at one. Check all coordinates on multiple small, nondegenerate inputs and include a nonzero regularization case.
Symbolic differentiation manipulates expressions. Finite differences evaluate nearby inputs and approximate a derivative. Automatic differentiation evaluates exact chain-rule operations for the chosen differentiable program, subject to floating-point arithmetic and conventions at nonsmooth operations. It is not finite differences without an explicit step size. Backpropagation is a reverse-mode instance of this idea.
At a ReLU kink, an ordinary derivative does not exist. A framework’s selected subgradient convention need not equal a central difference that straddles the kink. For a smooth tanh network, mismatches more directly suggest indexing, scaling, regularization, or chain-rule errors, though numerical extremes can still dominate. Passing selected gradient checks supports the tested implementation; it is not a theorem that every possible network and input is correct.
Optimization difficulties do not disappear when gradients are correct#
When is large, approaches and becomes small. Repeated small factors can attenuate derivatives through depth. Repeated large matrix factors can amplify them. Initialization, normalization, architecture, precision, and learning rate all interact. Gradient clipping limits a selected update magnitude; it does not prove the objective is well conditioned or repair a wrong gradient.
Initializing hidden units identically can preserve their symmetry: equal incoming parameters produce equal activations and equal gradient updates under the same deterministic training process. The units then fail to develop different features. Random initialization breaks this particular symmetry, but does not guarantee successful optimization. The lab uses seeded small nonzero random weights and zero biases so an experiment is reproducible and the distinction is visible.
The executed XOR demonstration begins near loss and reaches about after 2,500 steps with rate and seed 7 in the recorded environment. The derivative check is small, but this run is not evidence that all XOR points were learned to arbitrarily low error. A nonconvex optimizer can stall with some points still poorly separated. Inspect predictions and gradient norms, compare seeds and capacities under a predeclared protocol, and report failures rather than silently selecting a successful seed. Four synthetic training rows say nothing by themselves about real-world generalization.
Independent practice#
F foundation C standard course work T transfer S optional stretch L runnable lab or project. Attempt the complete set before opening its solutions.
For the one-unit example , derive the loss and all four parameter gradients. Explain why the zero gradient of does not make the gradient of zero.
Duplicate every row of a dataset. With an average data loss and a regularizer added once, should the objective and gradient change? Contrast with a summed data loss plus the same fixed penalty.
A gradient check fails for but passes for and . A different check evaluates ReLU exactly at zero. Explain why neither failure alone proves the backward program is wrong, and propose a more informative check.
Two hidden units start with identical incoming weights, biases, and output weights. Under full-batch deterministic gradient descent, explain why they can remain identical. Identify what random initialization changes and what it cannot guarantee.
A correctly differentiated network lowers XOR training loss to about but leaves two outputs close to . Classify what this supports, what remains unestablished, and two experiments that distinguish implementation error from optimization difficulty without claiming a real-world benchmark.
Implement the flat-parameter network in starters/neural.py. Use parameters, stable binary loss, mean gradients, and penalties only on weights. Check every parameter against central differences on three seeds, then record a training run, including any failure to fit.
Smallest useful hints#
For .01, start from and work backward, not from a guessed weight update. For .02, write the two averages explicitly. For .04, compare the two units’ equations after one update.
Complete solutions: G13#
Compare the first step where your work differs. A corrected answer is not yet an independent success.
G13.01Show solution
The hidden pathway still carries sensitivity
The forward values are , , . Then , , , and . The derivative with respect to uses the present activation zero; the derivative with respect to uses the nonzero output weight 3 and the sensitivity of the activation to its input. These are different paths. Substitution into the chain-rule formulas or a small finite-difference perturbation checks the result.
Back to G13.01G13.02Show solution
Reduction conventions are part of the model specification
The doubled average is , so both the mean data term and gradient are unchanged. The once-added penalty is also unchanged. For a sum, the data term and its gradient double but the fixed regularizer does not; its relative influence is halved. Duplicating observations does not create independent statistical information, even when it changes a badly specified training objective.
Back to G13.02G13.03Show solution
Check smoothness and numerical scale separately
At a tiny step, represented parameters or losses may become identical, and subtractive cancellation can dominate the quotient. Try a range of moderate steps and compare the expected region of decreasing error before rounding dominates. At ReLU zero the classical derivative is undefined; move to a nonzero input away from the kink or explicitly test the chosen nonsmooth convention. Use small finite inputs and nonzero weights, check multiple coordinates, and preserve the exact forward objective. Passing a better experiment provides local evidence, not a universal proof.
Back to G13.03G13.04Show solution
Symmetry can be preserved by the update rule
Equal incoming parameters imply equal activations. Equal output weights and activations imply equal reverse sensitivities, so each corresponding parameter receives the same update. Induction over iterations preserves equality. Independent initial weights break this exact symmetry and permit different features. They do not prove escape from every saddle, adequate capacity, a good learning rate, or generalization.
Back to G13.04G13.05Show solution
Optimization success is not binary
The run supports that the reported optimizer reduced this training objective. Outputs near indicate remaining uncertain or poorly separated examples; the run does not establish a perfect XOR fit or any out-of-sample utility. Compare analytic gradients to central differences on the current state, then compare a small predeclared set of initializations or a wider hidden layer while preserving data and objective. Inspect loss, logits, and gradient norms. Report every seed rather than selecting one after seeing results. These are synthetic functional experiments, not evidence about production data.
Back to G13.05G13.06Show solution
A reference with explicit parameter layout
The first entries contain rows of , the next contain , the next contain , and the final entry is . Each example contributes to a shared gradient vector by addition. The code computes all contributions before the training loop updates parameters. Tests include shape rejection, finite-value checks, numerical derivatives, and decreasing loss on a specified example; they do not require an invented guarantee of fitting every seed.
"""G13: one-hidden-layer tanh network, flat parameters, analytic backpropagation."""
import math
import random
try:
    from .ml import validate_xy, sigmoid, logit_loss
except ImportError:
    from ml import validate_xy, sigmoid, logit_loss


def initialize(d=2, h=2, seed=7):
    if type(d) is not int or type(h) is not int or not 1 <= d <= 64 or not 1 <= h <= 32:
        raise ValueError("bounded positive layer dimensions required")
    rng = random.Random(seed)
    W = [rng.uniform(-1,1)/math.sqrt(d) for _ in range(h*d)]
    return W + [0.]*h + [rng.uniform(-1,1)/math.sqrt(h) for _ in range(h)] + [0.]


def loss_grad(theta, X, y, h=2, lam=0.):
    n,d = validate_xy(X,y)
    if type(h) is not int or not 1 <= h <= 32 or len(theta) != h*d+2*h+1:
        raise ValueError("parameter vector does not match network shape")
    if not all(math.isfinite(v) for v in [*theta,lam]) or lam < 0:
        raise ValueError("finite parameters and nonnegative regularization required")
    bstart, vstart = h*d, h*d+h
    grad, loss = [0.]*len(theta),0.
    for x,target in zip(X,y):
        a = [math.tanh(math.fsum(theta[j*d+k]*x[k] for k in range(d))
                       +theta[bstart+j]) for j in range(h)]
        z = math.fsum(theta[vstart+j]*a[j] for j in range(h))+theta[-1]
        loss += logit_loss(z,target)/n
        dz = (sigmoid(z)-target)/n
        grad[-1] += dz
        for j in range(h):
            grad[vstart+j] += dz*a[j]
            du = dz*theta[vstart+j]*(1-a[j]*a[j])
            grad[bstart+j] += du
            for k in range(d):
                grad[j*d+k] += du*x[k]
    for i in [*range(h*d), *range(vstart,vstart+h)]:
        loss += .5*lam*theta[i]*theta[i]
        grad[i] += lam*theta[i]
    if not all(math.isfinite(v) for v in [loss,*grad]):
        raise ValueError("nonfinite network calculation")
    return loss,grad


def gradient_check(theta, X, y, h=2, lam=.03, step=1e-6):
    if not math.isfinite(step) or step <= 0:
        raise ValueError("positive finite difference step required")
    _,g = loss_grad(theta,X,y,h,lam)
    errors = []
    for i in range(len(theta)):
        a,b = list(theta),list(theta)
        a[i] += step
        b[i] -= step
        numerical = (loss_grad(a,X,y,h,lam)[0]-loss_grad(b,X,y,h,lam)[0])/(2*step)
        errors.append(abs(numerical-g[i])/max(1.,abs(numerical),abs(g[i])))
    return max(errors)


if __name__ == "__main__":
    X,y = [[0.,0.],[0.,1.],[1.,0.],[1.,1.]],[0,1,1,0]
    theta = initialize()
    print("scaled gradient discrepancy",gradient_check(theta,X,y))
    before = loss_grad(theta,X,y)[0]
    for _ in range(2500):
        _,g = loss_grad(theta,X,y)
        theta = [v-.2*dv for v,dv in zip(theta,g)]
print("XOR training loss", before, loss_grad(theta,X,y)[0])Readiness and continuation#
Derive an outer-product gradient on a new shape without copying the formulas. Predict which parameters receive a gradient when an activation is zero. Then implement a second hidden layer and compare hand-derived gradients with a framework, keeping tensor shapes and mean-versus-sum conventions explicit. Convolution, recurrent networks, optimizers with state, normalization, and large-scale training need additional analysis and experiments beyond this small network.